
Neo4j
You can connect to Neo4j to read and write to the Neo4j graph database. This capability is provided by the Neo4j plugin, which you need to install. See Installing plugins for installation instructions.
Through the connector recipe you will be able to perform different types of actions:
Export data from Dataiku to a Neo4j graph database
Import data from a Neo4j graph database to Dataiku.
Run Cypher queries in a Neo4j database using a macro.
How to set up
If you are a Dataiku and Neo4j admin user, follow these configuration steps right after you install the plugin. If you are not an admin, you can forward this to your admin and scroll down to the How to use section.
Create a Neo4j server configuration preset
All the components of the plugin use a preset containing the Neo4j server URI, username, password, and target database name. Use the connection URI provided for Neo4j drivers, accessible from the Dataiku server.
In Dataiku, navigate to Plugins > Neo4j > Settings > Neo4j server configuration and create a preset with your Neo4j credentials.
You can create multiple presets that connect to different Neo4j databases and you can set specific permissions for them.
How to use
We will explain the plugin components using a graph of football transfers as an example.
Export relationships recipe
Description
The goal of this recipe is to export a dataset containing relationships from Dataiku to a Neo4j graph database.
We have the following dataset in Dataiku of football transfers:
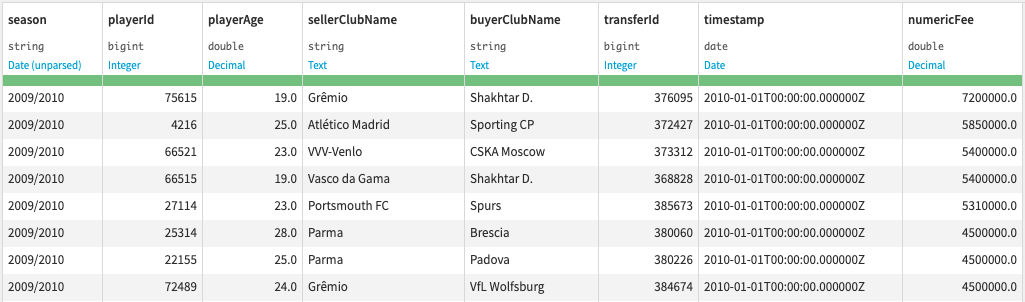
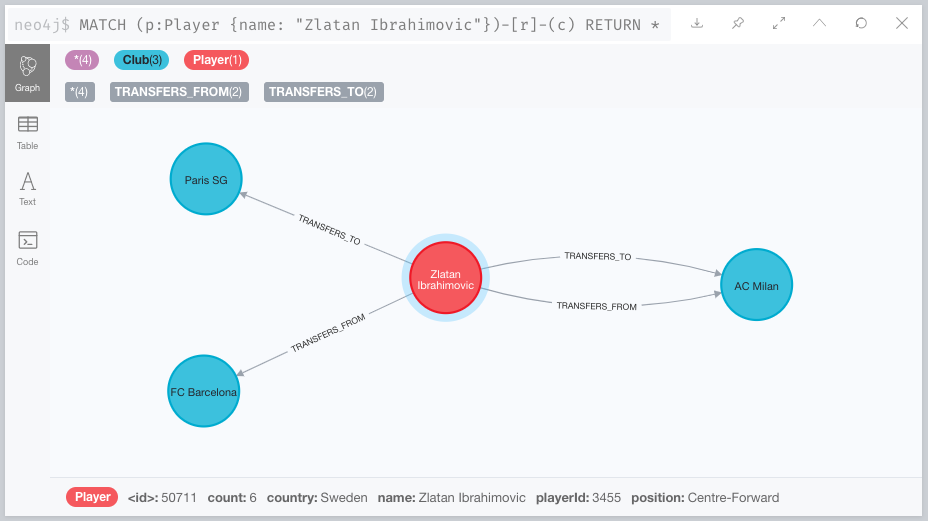
We want to create 2 types of nodes (Player and Club) and 2 types of relationships (TRANSFERS_TO and TRANSFERS_FROM) from this dataset in order to have the following graph in Neo4j:
(Club)<-[TRANSFERS_FROM]-(Player)-[TRANSFERS_TO]->(Club)
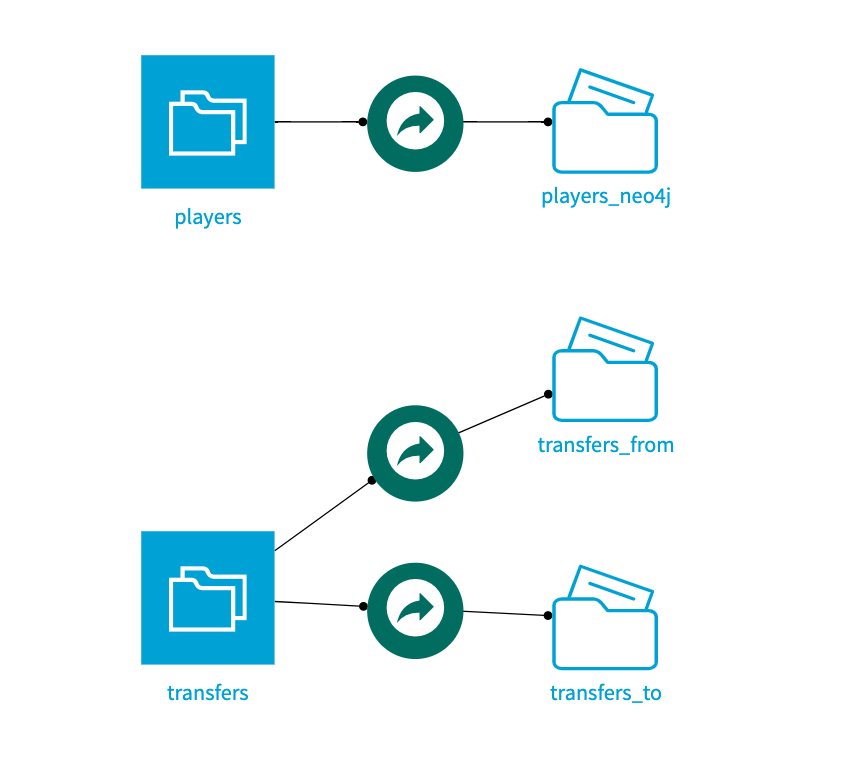
For that we will need to create two recipes, one for exporting the relationships ’TRANSFERS TO’, and one for exporting the second type of relationships, ’TRANSFERS FROM’.
First, create an Export relationships recipe from the + RECIPE button or from the right panel if your dataset is selected.
This recipe will create new nodes and relationships (and add their properties) from the input dataset. If some nodes and/or relationships already exist in the Neo4j database, their selected properties are updated with the input values, and new relationships are attached to the existing nodes.
The following recipe is filled to create the (Player)-[TRANSFERS_TO]->(Club) relationships with 2 properties (timestamp and fee).
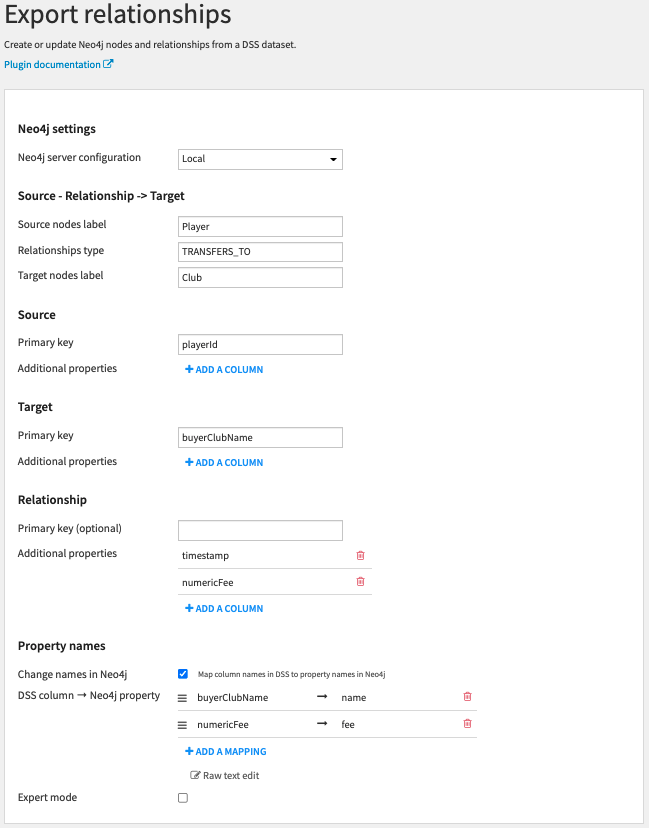
Settings
Neo4j settings
Select a preset defined in the plugin settings that contains your Neo4j server URI and credentials.
Source – Relationship -> Target
Enter the source and target node labels (they can be the same) and the relationship type that you want to create in Neo4j.
Source/Target:
Primary key: Select a dataset column that corresponds to the primary key of the nodes (used to check whether a node already exists, should be unique). The primary key column cannot contain null or empty values.
Additional properties: Select columns that correspond to other node properties that you want to add in Neo4j.
Relationship:
Primary key: for relationships, this parameter is optional.
Additional properties: Select columns that correspond to other relationship properties that you want to add in Neo4j.
Property names:
Change names in Neo4j: You can choose to rename the properties in Neo4j instead of using the Dataiku column names (useful when the source and target nodes have the same labels). For example, when the source and target nodes have the same labels but are 2 different columns in the Dataiku dataset, you can map both source and target columns to the same name.
If the parameter is selected, you will be able to map the Dataiku column names to the names you want to use in Neo4j.
Expert mode:
You can activate the expert mode in order to set additional parameters.
Extra properties:
Node count: If selected, nodes will have a count property that is incremented each time they are updated during the export.
Relationship weight: If selected, relationships will have a weight property that is incremented each time they are updated during the export.
Export parameters:
Batch size: Number of rows sent in each Cypher query commit (if you are using the “load from CSV files option”, this parameter corresponds to the PERIODIC COMMIT query hint of Neo4j).
Import data from CSV files: By default data are sent directly to the Neo4j graph database using a Bolt network connection. Select this parameter if you want to send data to the Neo4j import directory instead and use the
LOAD CSVCypher clause.Note
To use this option, you must create an output folder that is stored in an SCP/SFTP connection to Neo4j. See Import data from CSV files for requirements and configuration.
If selected, CSV file size controls the size of the CSV files. The dataset is split into multiple CSV files of the selected size that are sent to the output folder.
Delete nodes before run: If selected, nodes with selected labels and attached relationships will be deleted before exporting the relationships.
Ignore row when …:
Source node doesn’t exist: If the source node of a row doesn’t exist, then the row is skipped.
Target node doesn’t exist: If the target node of a row doesn’t exist, then the row is skipped.
Similarly, we can create the (Player)-[TRANSFERS_FROM]->(Club) relationships.
Export nodes recipe
We also have a dataset in Dataiku containing information about the football players:
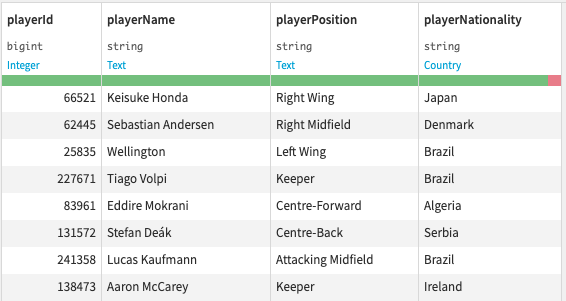
We want to use this dataset to add new properties to the Player nodes in the Neo4j database.
Now, create an Export nodes recipe.
This recipe will create new nodes (and add their properties) from the input dataset. If some nodes already exist in the Neo4j database, their selected properties are updated with the input values.
The following recipe is filled to add 3 new properties to the Player nodes (name, country and position) using playerId as the primary key to match nodes.
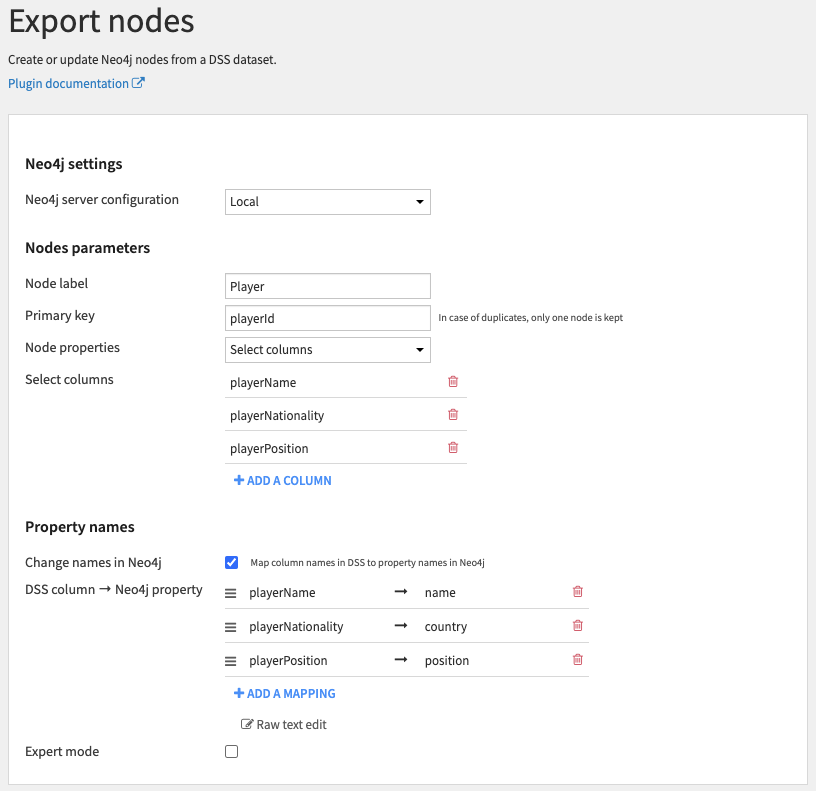
Settings work the same way as in the Export relationships recipe.
The complete flow described above looks like:
Here is an example of what the newly created graph looks like in the Neo4j desktop:
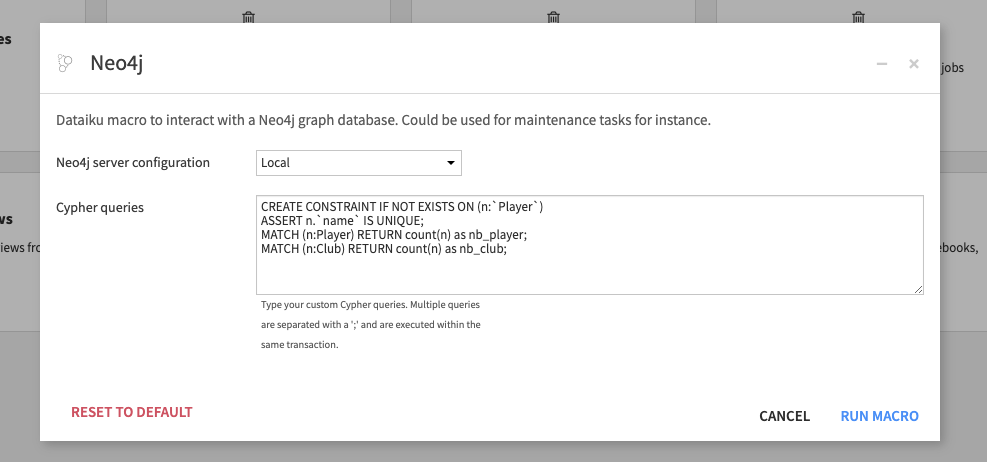
Macro
The macro can be used when a user needs to simply interact with the database and when no output Dataset is required. It could be used for instance to perform maintenance tasks on the database, create indices, test Cypher queries, delete nodes…
The macro can be used within a scenario to automate a process, for example exporting data to a Neo4j graph database and then running Cypher queries on the updated/new Neo4j graph database.
All queries in the macro are executed in a single transaction. If a query fails, the transaction is rolled back. Queries must be separated by a semicolon.
Dataset (import data from Neo4j)
The Dataset can be used to import data from Neo4j into Dataiku. It is available from the flow in + Dataset > Neo4j. This connector retrieves:
all nodes (and their properties) with a given label.
all relationships (and their properties) with a given type.
any results of a custom Cypher query.
Note that if you don’t enter any node label or relationship type, then it will retrieve a list of either all node labels or all relationship types.
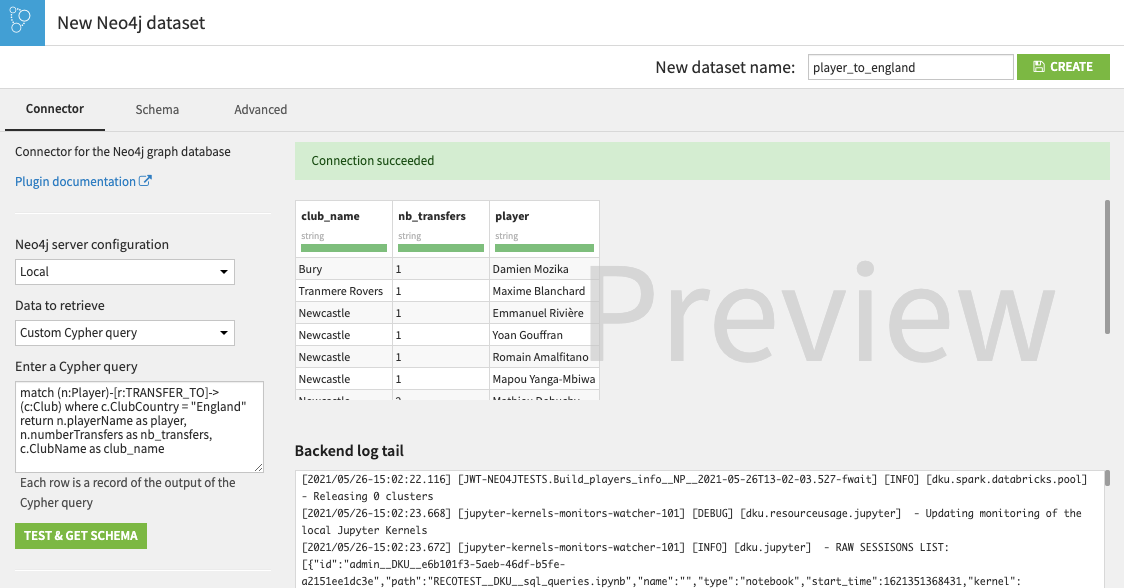
The resulting Dataiku Dataset can be used in a larger Flow and blended with other data sources as required, and could be the input of an ML model for example.
Additional info
Plugin limitations and improvements
Neo4j 4.4 or later required. The CSV export mode has additional restrictions described below.
Dataiku 9.0.0 and higher required.
Import data from CSV files
Note
In plugin version 1.5.0, this mode uses USING PERIODIC COMMIT, which was removed in Neo4j 5.
Use the default Bolt export mode with Neo4j 5 or later.
This CSV mode is also unavailable on Neo4j Aura because it requires access to the server import directory.
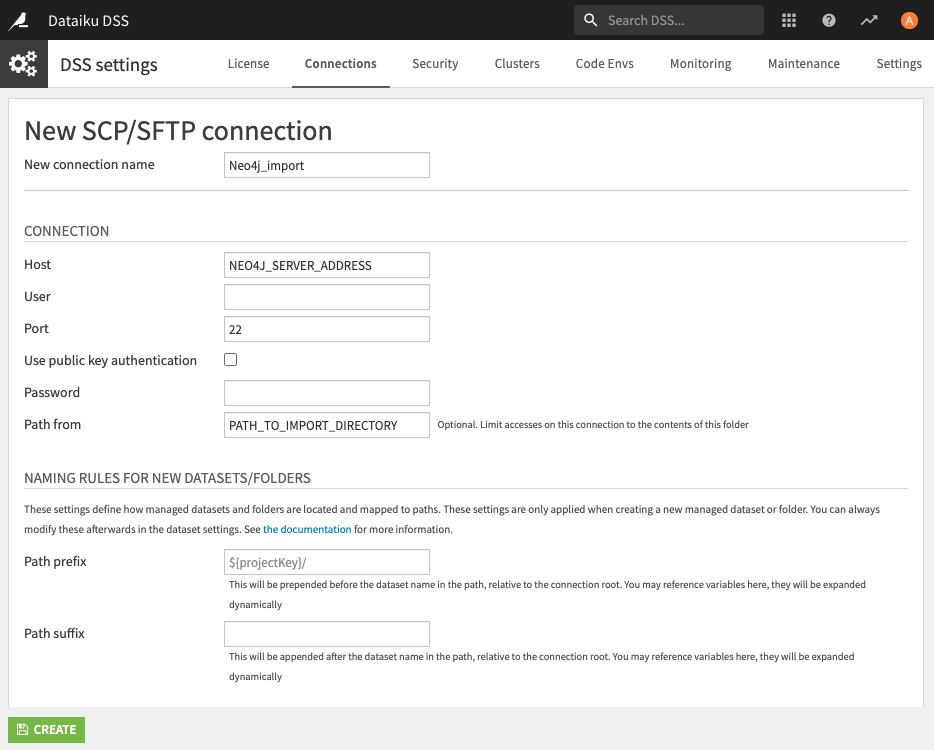
In order to import data from CSV files (using the LOAD CSV Cypher clause) in the 2 export recipes, you need to create an SCP/SFTP connection in Dataiku to the Neo4j import directory.
The output of the export recipes will be folders stored in this connection.
Dataiku Unix user must have SSH access to the machine hosting Neo4j.
In Dataiku, navigate to Administration > Connections > + New connection > SCP/SFTP and create a new connection with the Neo4j server address, Unix user, key or password authentication and enter the path to the Neo4j import directory.
Contributing
You are welcome to contribute to this plugin. Please feel free to use issues and pull requests in the GitHub repository.